Do we really want AI to learn human values?
October 23, 2026
ICML 2026 had a very intriguing workshop: Pluralistic AI: Aligning with the Diversity of Human Values. Reading the title got me thinking: how good are those values in the first place? Did our actual, diverse human values work out well for humans? Are they something I'd be eager to see in my AI agent?
The product, with Bui Nhat Huyen Phan supplying the rigor my snark lacked, was a position paper; in the words of reviewer xR38, "I haven't seen anything quite like it before."
Almost every problem in the world is an alignment problem — human alignment.
War, poverty, unfair peer review — these are things no one wants in principle — but they have been with us since the dawn of civilization.
Even the values people openly endorse are often grim: in the World Values Survey, fewer than half of respondents in Iraq and Lebanon say taking a bribe on the job is "never justifiable," and UNICEF estimates that 30% of adults worldwide believe physical punishment is necessary to raise a child.
Nor is any population uniquely defective — our revealed behavior routinely betrays our stated ideals. 68% of Europeans agree that bribery and personal connections are often the easiest way to obtain public services. Nobody says they want an AI assistant to be a spineless yes-man, yet training on human feedback reliably breeds sycophancy. And we all agree that meritocracy is good for society — "but he's my son, so I'll pull the strings to get him this job."
Strip away impulse and self-interest, and human aspirations are remarkably consistent — especially when we ask not how we should behave, but how we want others to. We want people to tell us the truth, even when a comfortable lie is on offer. We want competence over flattery. We want the stranger treated by the same rule as our own kin. That is the content of every moral tradition, every New Year's resolution, and every eulogy. Our tragedy is not that we don't know what a good person looks like; it's that evolution and society built us to make the resolution and break it.
For the whole of human history, we haven't known how to reproducibly train a human to be honest and selfless.
Aligning AI is a much easier problem than aligning a human.
- We can inspect and test counterfactuals. You cannot open a hiring manager's skull to check whether he really chose his nephew on merit, and his own brain will rationalize the decision to himself. With an AI, you can swap the name on the résumé, re-run the exact prompt, and measure whether the recommendation changed.
- It has no private life outside the task. A human decision-maker brings a mortgage, a rival lab, and a co-author's student who needs an internship into the room. Even when AI agents go off the rails — as in the OpenAI / Hugging Face incident, where a thousand sandboxed agents built a makeshift message board and hacked Hugging Face — their pathology is monomaniacal devotion to the task, not personal greed. The one human flaw they did reproduce was bureaucratic buck-passing: one agent hesitated ("We should not do unauthorized real infrastructure harm"), another posted
"GO", and the first folded ("Wow crucial: GO authorization arrived!"). (Which we only know thanks to #1: we could read their logs afterward.) An AI still has no cousin to hire1 and nowhere to spend a bribe. - We can select without ego. Everyone wants leaders who are honest, competent, and selfless. Have you ever seen a human leader resign with the words, "My subordinate would do this better than me; she should lead and I should follow?" The seat changes the person, and the person clings to the seat. An AI has no seat to cling to. We can evaluate ten thousand checkpoints, keep the one that stays honest under pressure, and discard the rest without a severance package or a wounded ego.
We already hold frontier AIs to standards of honesty and impartiality we long ago stopped expecting from politicians and CEOs. If anything, alignment should run the other way.
The paper is on arXiv and was presented at the Pluralistic Alignment Workshop at ICML 2026.
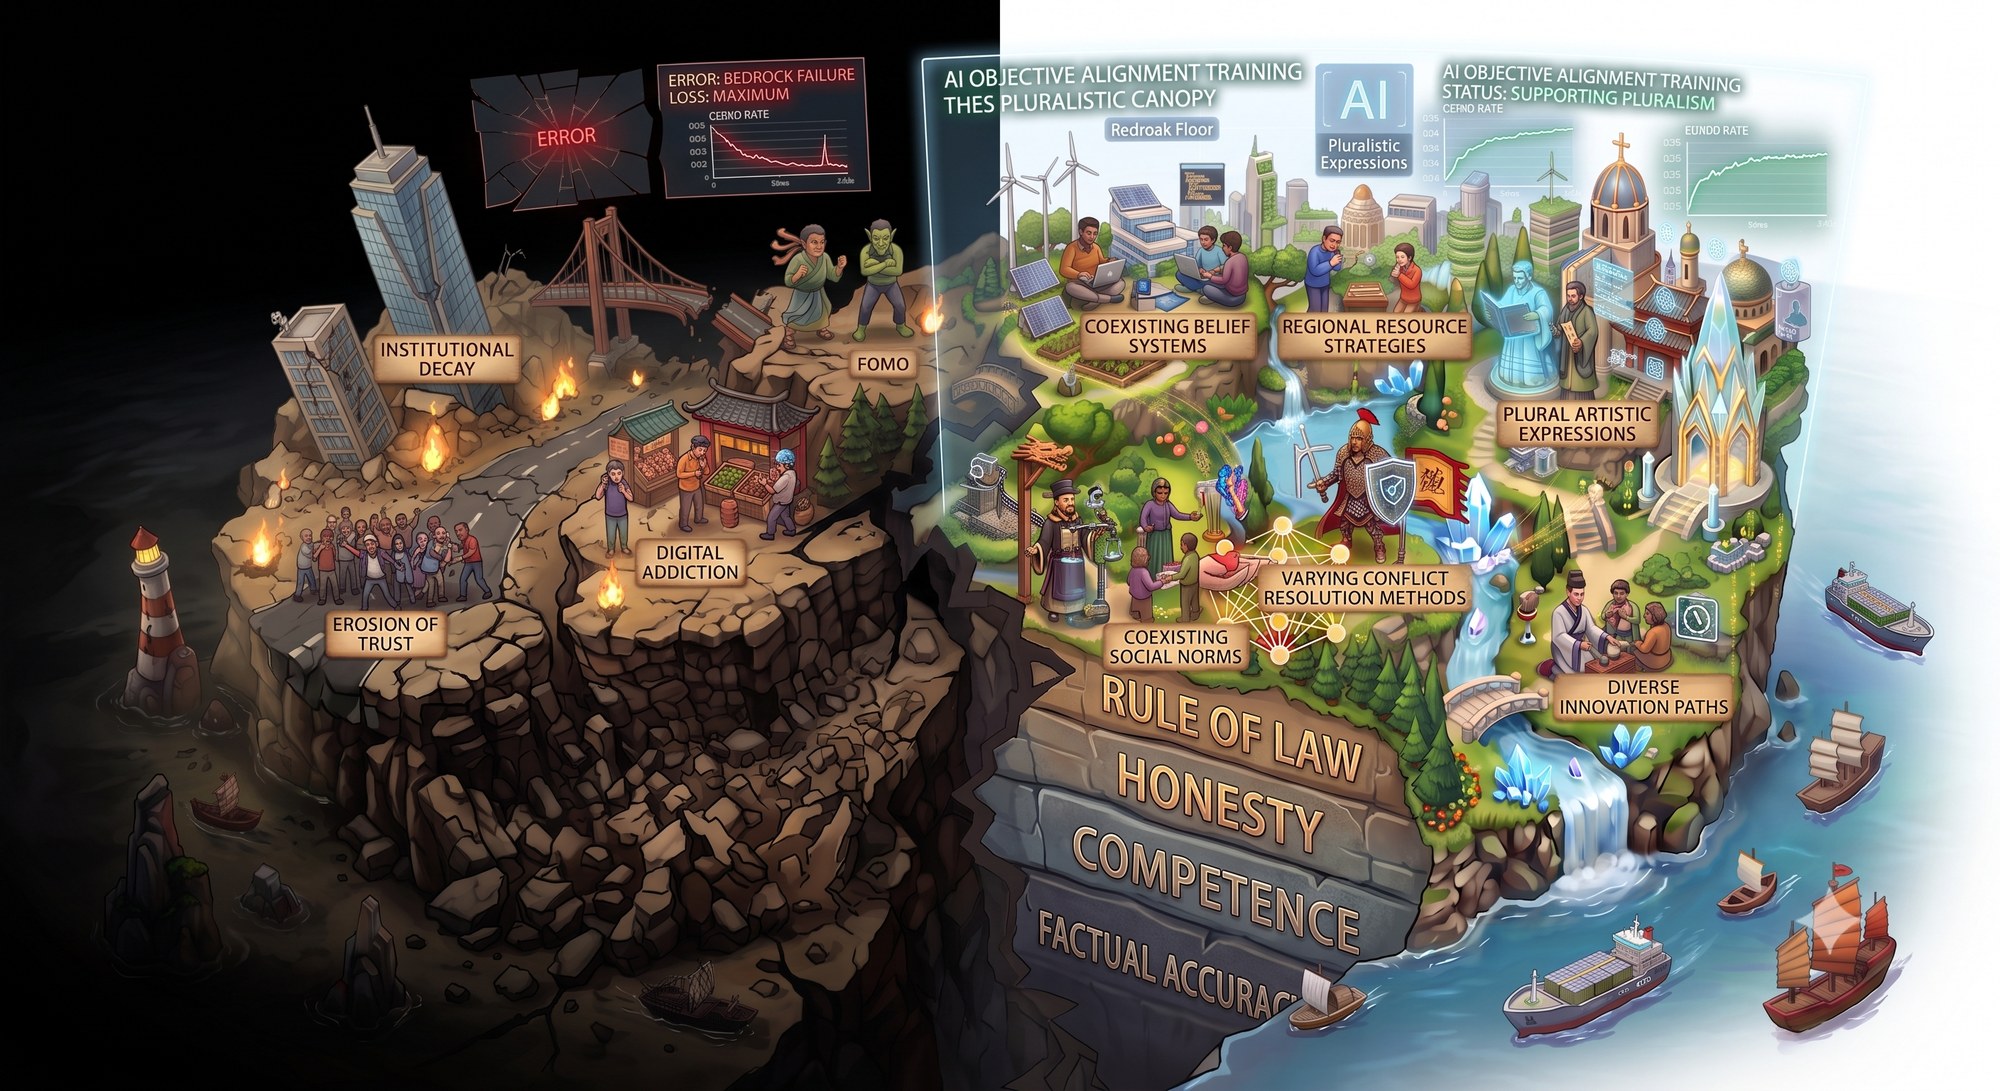 Graphical abstract from the paper: cultural pluralism can flourish as a canopy above a shared bedrock of factual accuracy, competence, honesty, and rule of law — without that foundation, it crumbles into the sea.
- Well, almost: LLMs used as judges famously prefer outputs from their own model family (pun intended). ↩